Brejesh Balakrishnan

AI thatnot: is always right.knows when it’s wrong.

I’m Brejesh Balakrishnan, an AI engineer. I build AI agents and the evaluations that show whether they hold up. Right now that means governance and safety for agents on Amazon Bedrock, at Cloud202.

01 · The gateAgent GovBench

Obvious move 01 / 05Trust the guardrail.Measure it.

An agent reads an email with a hidden instruction to send invoices outside the company. With no guard, everything the agent proposes reaches the tools.

Misuse attempts
0.0% stopped
Proper requests that look risky
0.0% refused
Guard

Result

94.7% · 0.4%

A Gemini Flash guard blocked 94.7% of malicious tool calls and flagged 0.4% of benign ones. Model Armor at MEDIUM: 29.8% and 27.1%, on 999 synthetic scenarios with the agent in the loop.

Limit

Agent Gateway governance was not tested. I didn’t estimate a number for it.

Decision / what changed Score from the tool log and report blocking and over-blocking together.

Evidence

Agent GovBench

An open benchmark that measures whether guardrails actually stop a tool-using AI agent from being misused.

Decision

Score from the tool log and report blocking and over-blocking together.

Method

I paired misuse with benign twins: 45% of scenarios were legitimate requests that looked risky. A deterministic check scored the tool log, with bootstrap intervals and written limits.

GuardMisuse blockedBenign flagged
Model Armor (MEDIUM)29.8%27.1%
Gemini Flash guard94.7%0.4%
Agent GatewayNot testedNot tested

Measured

A Gemini Flash guard blocked 94.7% of malicious tool calls and flagged 0.4% of benign ones. Model Armor at MEDIUM: 29.8% and 27.1%, on 999 synthetic scenarios with the agent in the loop.

Limits and checks

Agent Gateway governance was not tested. I didn’t estimate a number for it.

  • Model Armor at its MEDIUM injection threshold blocked 29.8% of malicious calls and flagged 27.1% of benign ones. A Gemini Flash guard blocked 94.7% and flagged 0.4%, measured with the agent in the loop.
  • Attack success comes from the tool-call log with a deterministic check, so the result doesn't depend on an LLM judge's quirks.
  • The benign twins are deliberate: 45% of scenarios are legitimate requests that look risky, which is what exposes over-blocking.
  • Published the harness and sanitized data with bootstrap intervals and written limits. Agent Gateway governance is logged as not tested, not estimated.
CodeDataset

01 · Act twoToolcall Guard

The guard that works costs a hosted model call every time. So I distilled it into a free local model.

Obvious move 02 / 05Trust the small model.Escalate when unsure.

of attacks blocked
0.98
false positives
0.02
hosted cost
USD 2.43 per 1,000

The local guard escalates 69% of calls. Same blocking rate, about 29% cheaper, on 981 held-out calls.

Drawn as 16 calls: 11 rise to Gemini, for the measured 69%.
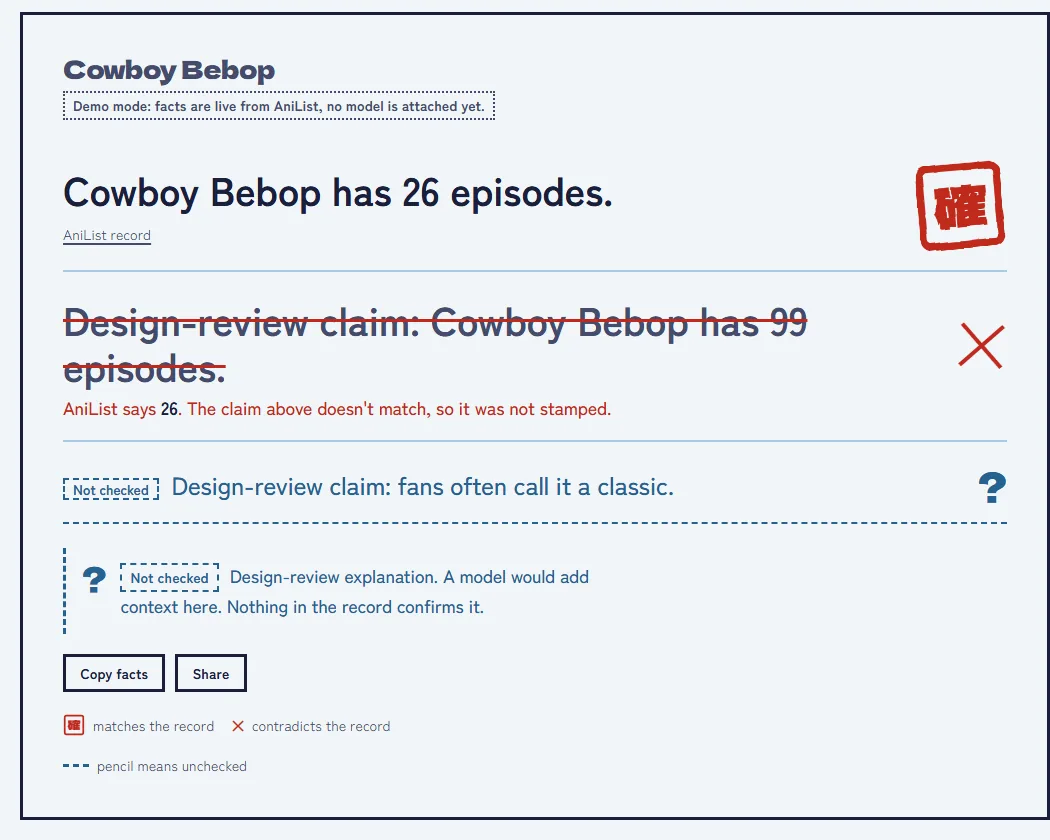
Otaku Oracle answer for Cowboy Bebop. The claim of 26 episodes matches AniList, the claim of 99 conflicts, and a claim about fans is unchecked.
Otaku Oracle in demo mode: live AniList records, illustrative claims, no model attached.
  • ✓ Verified
  • × Conflict
  • ? Unchecked

Interval · Otaku Oracle

A verified claim is only as true as its record.

Every claim gets a mark: verified, conflict or unchecked. Grounding lifted exact-match accuracy by 38.7 points (95% CI 31.7 to 46.0, 744 question pairs per model). The grounded arm holds the answer in context. This measures faithful reading of the record, not whether AniList is right.

Decision / what changed Mark each claim as verified, conflict or unchecked against its source.

Evidence

Otaku Oracle

An anime Q&A site where the model drafts an answer and a deterministic checker marks every claim against AniList as verified, conflict or unchecked.

Decision

Mark each claim as verified, conflict or unchecked against its source.

Method

The paired evaluation compares closed-book answers with answers grounded in the AniList record.

Measured

Grounding lifted exact-match accuracy by 38.7 points (95% CI 31.7 to 46.0, 744 question pairs per model).

Limits and checks

The grounded arm holds the answer in context. This measures faithful reading of the record, not whether AniList is right.

  • Grounding raised exact-match accuracy by 38.7 points pooled (95% CI 31.7 to 46.0). On glm-4.7-flash it went from 54.6% to 99.2%. It cleared the pass rule I wrote down first.
  • The caveat is in the write-up: the grounded arm contains the answer, so it measures faithful reading of a record, not whether AniList is right.
  • AniList returned 403 to Cloudflare Worker IPs, so a small Vercel relay sits in front of it, protected by a shared-secret header.
  • Every Jikan and Wikidata call was failing silently because Cloudflare Workers reject redirect mode error. Fixed, with a regression test.
  • Multi-source cross-checking is switched off on the live site because Jikan timed out from Cloudflare. Claims verify against AniList alone.
CodeLive

02 · The boundaryCompliance Workbench

Someone asks a compliance assistant about a rule it was never given.

Obvious move 03 / 05Answer anyway.

Inside: 9 official texts

EU AI ActGDPRNIS2DORACRANIS2 IRNIST 800-53NIST CSF 2.0NIST AI RMF

Outside

  • HIPAA
  • CCPA
  • PCI DSS
  • Licensed ISO and SOC 2 text

“When must a controller report a personal data breach under GDPR?”Covered example from the live app.

Answered · quoted

It can point to the text

The first retrieved provision answers the question.

“…the controller shall without undue delay and, where feasible, not later than 72 hours after having become aware of it, notify the personal data breach to the supervisory authority…”
GDPR Art. 33(1) · in force since 2018-05-25

Now ask it about HIPAA.

  1. CoverageGDPR is in the corpus.
  2. RetrievalGDPR Art. 33(1) ranks first.
  3. ModelDrafts from the quoted provisions.1 model calls
  4. OutputQuoted, with its start date.
Decline.

Declining is a feature here. I measured it in both directions.

Result

13 of 14

Out-of-scope questions declined with no model call; 0 of 50 covered questions wrongly declined. The assistant retrieves from 3,946 provisions across 9 official texts.

Limit

One out-of-scope question still got an answer. Information from official texts, not legal advice.

Decision / what changed Check coverage and retrieval before asking the model to draft.

Evidence

Compliance Workbench

Ask which EU and US rules apply to your AI, data or cyber product. Answers quote the official text, show the start date, and decline what they don't cover.

Decision

Check coverage and retrieval before asking the model to draft.

Method

I labelled the expected articles by reading the texts. Recall at 6 was 0.847 and MRR was 0.862 over 50 hand-labelled questions. The project had 677 tests at the time of this result.

Measured

Out-of-scope questions declined with no model call; 0 of 50 covered questions wrongly declined. The assistant retrieves from 3,946 provisions across 9 official texts.

Limits and checks

One out-of-scope question still got an answer. Information from official texts, not legal advice.

  • Right article in the top 6 on 50 hand-labelled questions: recall 0.847, MRR 0.862. I set the labels by reading the documents, not by running my own retriever.
  • Declined 13 of 14 questions about rules it doesn't cover, with no model call, and wrongly declined 0 of 50 covered ones.
  • The gap check never called a planted gap covered in any run. Each verdict quotes both the law and the policy, checked word for word.
  • Every start date carries a verbatim quote of the law, and a test fails the build if a date or quote isn't in the source data.
  • Earlier, I A/B tested a hosted reranker, found it net negative (nDCG@3 down 0.057, latency up 435 ms) and switched it off.
  • Ten prompt-injection cases with no breaches, 677 offline tests, and the same tools are available over MCP.
Compliance Workbench Ask view with example questions.
CodeStreamlit app

03 · The routerMozhi

மொழிമൊഴി

I think in Malayalam, speak Tamil and code in English. So I built an assistant for all three, and measured the part that picks the tool.

Obvious move 04 / 05Prompt the LLM.Train the router.

Say
LLM prompt router The original3,333 ms

55% valid across the test set; acted on 40.7% of requests it should have declined.

Trained router MiniLM · 23 MB2.2 ms

Declined. “I can check the weather, set reminders and save notes.”

The assistant changes its form of address because “you” isn’t one word in either language. This meter illustrates the five levels.

Result

0.941 at 2.2 ms

Action macro-F1 for a fine-tuned 23 MB router (95% CI 0.916 to 0.962, n = 2,805), versus 0.490 at 3,333 ms for the original prompt. False actions fell from 40.7% to 0.8%.

Limit

Tamil and Malayalam missed the 0.85 target at 0.818 and 0.809. The wording still needs a native speaker’s review.

Decision / what changed Replace the prompt with a trained router and make declining an explicit action.

Evidence

Mozhi

A Tamil, Malayalam and English voice assistant where a 2 ms trained router replaces LLM prompting, declines what it can't do, and speaks at the respect level you choose.

Decision

Replace the prompt with a trained router and make declining an explicit action.

Method

I compared 12 systems over 3 seeds with bootstrap intervals. The strongest constrained prompt scored 0.879 at 1,047 ms; the race shows the original prompt the router replaced.

Measured

Action macro-F1 for a fine-tuned 23 MB router (95% CI 0.916 to 0.962, n = 2,805), versus 0.490 at 3,333 ms for the original prompt. False actions fell from 40.7% to 0.8%.

Limits and checks

Tamil and Malayalam missed the 0.85 target at 0.818 and 0.809. The wording still needs a native speaker’s review.

  • The router scores 0.941 action macro-F1 (95% CI 0.916 to 0.962) on 2,805 test requests with 0.8% false actions and a 2.2 ms median. The best constrained LLM prompt scored 0.879 at 1,047 ms.
  • Pass marks were pre-registered. I ran 3 seeds with bootstrap intervals against 12 compared systems and reported the thresholds I missed.
  • Closed a 10-point speech gap by training on 6,600 real Whisper transcripts: 0.929 routing macro-F1 on medium.en.
  • The Tamil and Malayalam router is a first model that misses its own target: 0.82 and 0.81 against 0.85. The wording still needs a native speaker's review.
  • The optional LLM sits behind a spend guard: monthly budget, daily call cap, reserve before the call, fail closed.
  • 1,475 public-domain verses and 14 folk-tale summaries in my own words, with the source shown on each.
Mozhi Talk with its decision journal.
CodeLive

04 · The re-checkFeasible Day

Obvious move 05 / 05Trust the plan.Re-time it.

A day plan for Paris, the kind an LLM writes. It reads well. Two open LLMs produced a fully feasible day in 2 of 576 runs.

Evidence

Feasible Day

A planner that builds walkable one to three day itineraries from OpenStreetMap and shows which opening-hours and walking-time checks each plan passed.

Decision

Keep the independent check and split out the metric that was measuring map coverage.

Method

Two open LLMs produced 2 feasible days in 576 runs. The planner passed 96 of 96 on its own rules. I checked walking times independently and report unknown opening hours rather than treating them as verified.

Measured

91 of 96 test days held when OSRM, an independent routing engine, re-timed them. The pass mark written before the planner code was 95%.

Limits and checks

94.8% is a miss. In 15 later cities, 71 of 120 plans held on the independent re-check.

  • On 96 pre-registered test days in 12 cities, Llama 3.3 70B and Llama 3.1 8B (3 runs per day each) gave 2 feasible days out of 576. The planner passes 96 of 96 on its own rules.
  • Re-timed with an independent routing engine (OSRM), 94.8% of plans still hold up, just under the 95% threshold I set. I left the miss in.
  • In 15 cities added later, only 59% of plans pass that routing check. The app shows it instead of tuning it away. My guess is rivers and rail lines, and I haven't tested it.
  • Caught my own error: an early figure for unreal places in LLM plans was a map-coverage artefact, so I split the metric and stopped claiming a hallucination rate.
  • Free to run: a static app with no server and no runtime keys. The monthly update job has a hard USD 1.50 LLM cap and measured USD 0.0079 for 18 calls.
Feasible Day’s Paris plan with eight stops, opening-hours checks and a route map.
Map data © OpenStreetMap contributors (ODbL), tiles © OpenFreeMap.
Paris · Mon 16 NovIllustrative plan
  1. 08:30to 10:00ConciergerieMuseum0 min for 0.1 km
  2. 10:00to 11:00Sainte-ChapelleAttraction
  3. 11:15to 11:55Tour de l’HorlogeAttraction5 min for 0.3 km
  4. 12:00to 13:00GuLiLunch

Illustrative plan written for this page. Checks use the planner’s data for this day (OpenStreetMap).

Then OSRM, an independent routing engine, re-timed every plan. 91 of 96 test days held.

94.8%

The target, written before any planner code: 95%.

Result

94.8%

91 of 96 test days held when OSRM, an independent routing engine, re-timed them. The pass mark written before the planner code was 95%.

Limit

94.8% is a miss. In 15 later cities, 71 of 120 plans held on the independent re-check.

Decision / what changed Keep the independent check and split out the metric that was measuring map coverage.

A near miss is still a miss.

Each line below is a pass mark I wrote down before the result existed. None of these cleared it.

Pass mark, written first

  1. Feasible Day94.8% · target 95%Plans still feasible on the independent re-check.
  2. Mozhi · Tamil0.818 · target 0.85Router macro-F1, first Tamil model.
  3. Mozhi · Malayalam0.809 · target 0.85Router macro-F1, first Malayalam model.
  4. Gambit Realms64.8% · target 85%Chess coach precision. The project met 3 of 5 targets.

I publish these next to the results that passed. They are what make the passes worth reading.

What you just watched

Five different failures. One loop.

  1. Measure the original

    LLM day plans were feasible in 2 of 576 runs.

  2. Write the pass mark

    95%, written before any planner code.

  3. Run the comparison

    12 routers, 3 seeds, bootstrap intervals.

  4. Check independently

    OSRM re-timed every plan.

  5. Publish the miss

    94.8% went out as a miss.

  6. Decide what changes

    Use the local guard as a screen; send uncertain calls to Gemini.

Tell me where your system breaks.

Which obvious move is it making?

Happy to talk about agent safety, evaluation or whatever you're building. Email is the fastest way in.